DNA sequencing technologies are laboratory methods that determine the order of nucleotide bases in DNA, allowing scientists to read and analyze genetic information. Researchers use these technologies to investigate genes, identify genetic variants, study microorganisms, and compare genomes across different organisms.
Sequencing has become an essential tool in modern biological research, supporting discoveries in genetics, medicine, biotechnology, and environmental science. Advances in sequencing methods have made it possible to examine far more DNA in less time than earlier techniques allowed.
Different technologies offer distinct advantages in accuracy, read length, speed, and cost. Choosing the appropriate method depends on the biological question, sample quality, and amount of genetic information researchers need.
What Is DNA Sequencing?
DNA sequencing is the process of determining the precise order of four nucleotide bases within a DNA molecule: adenine (A), thymine (T), cytosine (C), and guanine (G).
These bases form sequences that contain genetic information. By reading them, scientists can examine genes, identify differences between DNA samples, and investigate how genetic changes affect biological functions.
Sequencing can target a single gene, selected genomic regions, or an organism’s entire genome. It can also analyze DNA recovered from environmental samples rather than directly collected organisms.
For example, environmental DNA in biodiversity monitoring allows researchers to investigate which organisms may be present in water or soil by analyzing genetic material they leave behind.
How DNA Sequencing Works
Although sequencing technologies use different detection methods, most research workflows follow several common stages.
- DNA extraction: Researchers isolate DNA from cells, tissues, microorganisms, or environmental samples.
- Sample preparation: DNA is processed into a sequencing library, often involving fragmentation and attachment of specialized adapter sequences.
- Sequencing: An instrument measures signals associated with DNA bases and generates sequence reads.
- Data processing: Software converts instrument signals into nucleotide sequences and evaluates read quality.
- Sequence analysis: Researchers compare reads with reference genomes or assemble them to investigate genetic information.
The exact preparation and analysis steps vary by platform. Some methods produce short, highly accurate reads, while others generate much longer sequences that help resolve complicated genomic regions.
Sanger Sequencing: The Chain-Termination Method
Sanger sequencing was developed during the 1970s and became one of the foundational methods of molecular genetics.
The method uses DNA polymerase to copy a DNA template. Alongside ordinary nucleotides, the reaction contains modified nucleotides called dideoxynucleotides, which terminate DNA strand extension when incorporated.
This produces DNA fragments of different lengths. Modern Sanger sequencing instruments separate the fragments through capillary electrophoresis and identify their terminal bases using fluorescent signals.
Sanger sequencing is particularly useful for examining individual genes, checking specific variants, and confirming results from other sequencing methods.
However, it processes relatively few DNA fragments per run compared with high-throughput technologies, making it less practical for large-scale genome sequencing.
Next-Generation Sequencing: Reading Millions of Fragments
Next-generation sequencing (NGS) refers to high-throughput methods that analyze many DNA fragments in parallel.
Instead of reading one DNA fragment at a time, these systems generate large collections of sequence reads during a single run. Computational tools then align or assemble the reads to reconstruct genetic information.
NGS supports applications such as whole-genome sequencing, targeted gene panels, cancer research, and microbial community analysis.
Illumina Sequencing
Illumina sequencing commonly uses sequencing by synthesis. Prepared DNA fragments attach to a flow cell, where they are amplified into clusters.
During sequencing, fluorescently labeled nucleotides are incorporated into growing DNA strands. Imaging systems identify the incorporated bases during repeated cycles.
Illumina platforms are widely used because they can produce large quantities of accurate short-read data. Their main limitation is that short reads can be difficult to place uniquely within highly repetitive genomic regions.
Ion Torrent Sequencing
Ion Torrent sequencing detects hydrogen ions released when DNA polymerase incorporates nucleotides into a growing DNA strand.
The instrument measures changes associated with these ions using semiconductor sensors rather than fluorescent imaging.
This approach supports targeted sequencing applications, although accurately determining the number of repeated identical bases can present challenges.
Long-Read DNA Sequencing Technologies
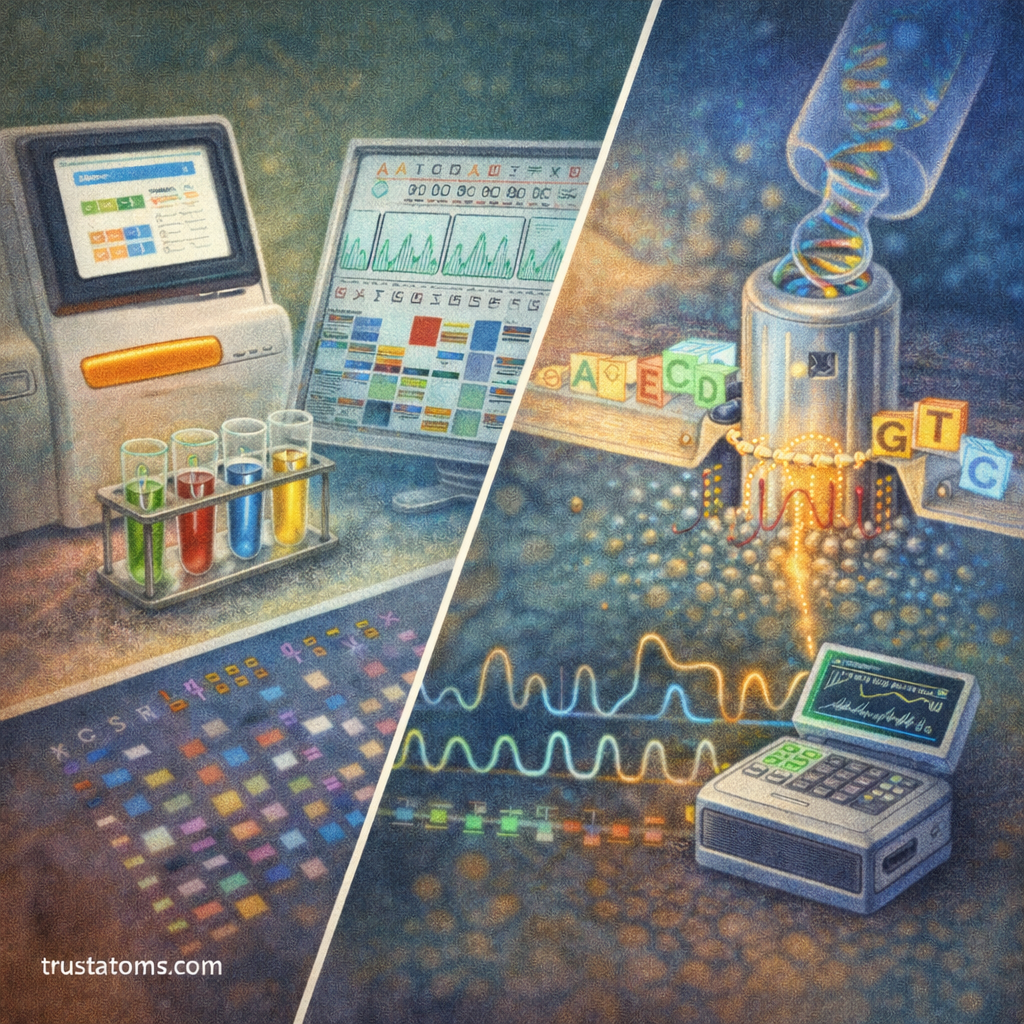
Long-read sequencing technologies analyze extended DNA molecules, making it easier to examine repetitive sequences and complex genome arrangements.
Long reads can span regions that would otherwise require many short fragments to reconstruct, improving certain types of genome assembly and variant detection.
PacBio Single-Molecule Sequencing
Pacific Biosciences sequencing observes DNA synthesis by individual polymerase molecules. Its circular consensus approach can repeatedly read the same DNA molecule to generate highly accurate long reads.
These reads are useful for genome assembly, examining repeated sequences, and detecting complex genetic changes.
One important application is enhanced detection of structural variations in genomes, including large insertions, deletions, and rearrangements that may be difficult to resolve with short reads.
Nanopore Sequencing
Nanopore sequencing measures changes in electrical current as a DNA molecule passes through a tiny pore.
Software interprets the electrical signal to estimate the nucleotide sequence. Because the technology reads individual molecules, it can produce long reads and provide sequence information while a run is still underway.
Some nanopore instruments are compact enough for field use. However, sample preparation, sequencing accuracy, and data requirements vary depending on the instrument and application.
Comparing Major DNA Sequencing Methods
| Technology | Typical Strength | Common Application |
|---|---|---|
| Sanger | Accurate analysis of individual DNA regions | Variant confirmation |
| Illumina | High-throughput, accurate short reads | Whole-genome and targeted sequencing |
| Ion Torrent | Semiconductor-based nucleotide detection | Targeted gene panels |
| PacBio | Highly accurate long reads | Genome assembly and structural variants |
| Nanopore | Long reads and real-time analysis | Field sequencing and complex genomes |
No single sequencing technology is ideal for every research question. Scientists consider read length, accuracy, throughput, sample quality, available equipment, and analysis costs when selecting a method.
A Practical Example: Identifying a Genetic Variant
Imagine researchers studying a family affected by a suspected inherited disorder. They want to determine whether affected family members share a particular DNA variant.
The researchers could sequence selected genes associated with the condition and compare the resulting sequences with a reference genome.
If the reference contains the sequence ACGTAC but a patient’s DNA contains ACGTTC at the same location, the difference represents a single-nucleotide substitution.
Researchers would then examine whether the variant affects a gene’s function, whether it occurs in affected relatives, and whether existing evidence supports a connection to the disorder.
Finding a DNA difference does not automatically establish that it causes disease. Many genetic variants are harmless, and interpreting their significance requires additional evidence.
Applications of DNA Sequencing in Biology
Medical and Genetic Research
DNA sequencing helps researchers investigate inherited disorders, cancer-associated mutations, and genetic differences that influence responses to certain medicines.
Genomic sequencing in molecular biology examines how analyzing extensive DNA sequences reveals genome organization and variation.
Microbial and Environmental Research
Sequencing allows researchers to investigate microorganisms in soil, oceans, and other environments, including organisms that are difficult to culture in laboratories.
Metagenomics, the study of genetic material from environmental samples, relies heavily on sequencing technologies to investigate microbial diversity and biological functions.
Evolutionary and Population Research
Scientists compare DNA sequences to investigate genetic relationships among organisms and changes in populations over generations.
According to evolutionary biology, genetic differences accumulate and change through processes such as mutation, natural selection, and genetic drift. Sequencing provides evidence researchers use to reconstruct evolutionary relationships and study population history.
Challenges in Sequencing and Data Analysis
Generating DNA sequences is only part of a sequencing project. Researchers must also evaluate data quality and determine what the results mean.
Common challenges include sequencing errors, contamination, incomplete genome coverage, repetitive DNA regions, and difficulties interpreting unfamiliar genetic variants.
Bioinformatics tools and computational analysis are essential for managing and interpreting sequencing data.
These tools help align sequence reads, assemble genomes, identify variants, and compare genetic information across samples.
How DNA Sequencing Is Advancing
Sequencing research continues to focus on improving accuracy, reducing costs, simplifying sample preparation, and expanding the ability to analyze difficult genomic regions.
Long-read technologies are helping researchers investigate complex genome structures, while portable instruments support sequencing outside traditional laboratories.
Improvements in computational analysis are also making it easier to process large datasets and interpret genetic differences. However, reliable conclusions still depend on appropriate study design, careful quality control, and biological validation.
Frequently Asked Questions
What is the difference between Sanger sequencing and next-generation sequencing?
Sanger sequencing typically examines individual DNA regions, while next-generation sequencing analyzes large numbers of fragments simultaneously. Sanger remains useful for targeted applications, whereas NGS is better suited to many large-scale studies.
Why are long DNA reads useful?
Long reads can span repetitive regions and complex genetic rearrangements that short reads may not resolve easily. They are especially useful for genome assembly and structural variant analysis.
Can DNA sequencing identify every genetic disease?
No. Sequencing can identify many genetic variants, but some changes are difficult to detect or interpret. A diagnosis may also require clinical information, additional laboratory testing, and evidence connecting a variant to a particular condition.
DNA sequencing technologies allow researchers to investigate genetic information at scales ranging from individual genes to complete genomes. Sanger sequencing, high-throughput short-read methods, and long-read technologies each offer advantages for different scientific questions. Selecting an appropriate method and carefully interpreting the resulting data are essential for producing reliable findings in medicine, genetics, and environmental research.
Sources: National Human Genome Research Institute, DNA Sequencing Fact Sheet; National Center for Biotechnology Information, Bookshelf resources on DNA sequencing; National Academies of Sciences, Engineering, and Medicine, Toward Precision Medicine.